 Befrey
Deploying artificial intelligence in today’s regulatory climate requires navigating a complex web of legal mandates. Organizations must master GDPR and AI: How to Ensure Compliance When Working with Data if they wish to innovate without risking catastrophic penalties. The General Data Protection Regulation establishes strict boundaries for processing personal info within machine learning ecosystems. Modern artificial intelligence data protection rules demand total transparency, lawful processing bases, and robust algorithmic accountability. Companies that fail to adapt their EU privacy regulations for machine learning risk massive fines, mandatory model deletion, and severe brand damage. Achieving full alignment with European data privacy standards is not merely a legal obligation; it is a critical competitive advantage for modern digital enterprises.
GDPR Compliance for Artificial Intelligence Training Data
Ingesting massive datasets into machine learning algorithms creates immediate compliance hurdles under European law. Organizations must ensure that every record used to train, fine-tune, or validate a model has a verified legal origin. Scraped web content, customer logs, and vendor feeds frequently contain protected personal details that cannot be processed arbitrarily. Data engineering teams must audit training sets to eradicate unlawful personal identifiers prior to model training.
If personal information remains embedded in training data without valid legal grounds, the resulting model parameters may be legally compromised. Regulators possess the authority to order algorithmic recourse, forcing organizations to erase trained model weights. To mitigate this risk, engineering pipelines must implement strict data filtering, tokenization, and sanitization routines. Maintaining comprehensive data provenance logs ensures that every sample can be traced back to its original collection point and legal authorization.

Legitimate Interest Legal Basis for AI Machine Learning
Selecting the proper legal basis is the foundational step for any lawful machine learning architecture. While explicit consent is often considered the cleanest path, obtaining it for millions of data points is practically impossible. Consequently, many organizations attempt to rely on the legal basis of legitimate interest for processing personal information. However, relying on this legal ground requires passing a rigorous three-part test.
First, the organization must articulate a clear, lawful objective for training the artificial intelligence system. Second, the processing must be demonstrably necessary to achieve that specific business objective. Third, the organization’s business interests must never override the fundamental rights and privacy expectations of individual data subjects. Conducting a formal Legitimate Interest Assessment (LIA) provides written evidence of this delicate balancing act. If data subjects object to processing, the organization must instantly halt model training unless compelling legal grounds override those individual rights.
Privacy by Design in Artificial Intelligence Development
Embedding compliance into the core architecture of your technical ecosystem is a statutory mandate. Technical teams cannot treat legal compliance as an afterthought added right before software deployment. Data protection principles must guide every architectural choice from dataset curation to model deployment. Implementing data minimization techniques ensures that algorithms only ingest the absolute minimum necessary information.
Engineers should leverage advance techniques like pseudonymization, differential privacy, and federated learning. Federated learning allows models to train on decentralized edge devices without centralizing personal data. Synthetic data generation can also replicate real-world statistical distributions without exposing actual human records. Privacy settings within deployed software tools must default to the most restrictive configurations possible. By enforcing structural privacy, organizations significantly compress their operational exposure and reduce potential data breach impact.
Data Protection Impact Assessment for AI Systems
High-risk processing operations automatically trigger the statutory obligation to complete a formal assessment. Artificial intelligence applications routinely involve large-scale processing, automated profiling, and systematic monitoring. Conducting an extensive risk review before writing code helps identify structural vulnerabilities early. This formal document must detail every aspect of data flow, processing logic, and potential harm to individuals.
The risk assessment must evaluate potential algorithmic bias, security vulnerabilities, and transparency barriers. Risk mitigation strategies must be explicitly documented and assigned to designated engineering leads. Furthermore, the assessment must be continuously updated whenever the underlying algorithm or data source changes. Supervisory authorities can demand to inspect these documents at any time during an inquiry. Maintaining exhaustive, living documentation proves proactive accountability and shields executives from personal liability.

Automated Decision-Making and Profiling Under GDPR
Article 22 establishes a general prohibition against fully automated decisions that produce legal or similarly significant effects on individuals. AI systems used for credit scoring, recruitment screening, tenant evaluation, or medical triage fall under strict scrutiny. Individuals have the absolute right not to be subjected to decisions based solely on automated processing. Organizations must build robust human-in-the-loop oversight mechanisms into automated operational workflows.
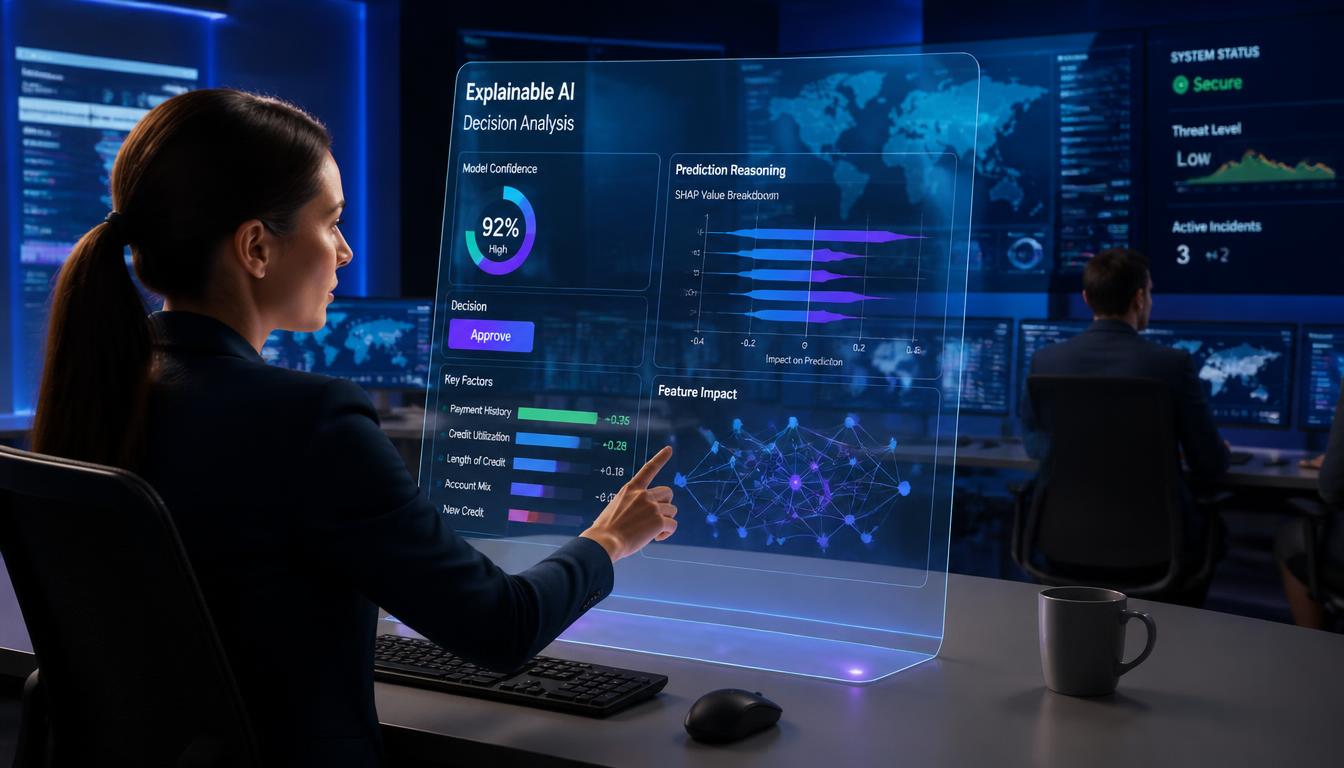
Human reviewers must possess real authority and technical competency to override machine predictions. Merely rubber-stamping an automated outputs does not satisfy statutory requirements. Furthermore, companies must provide data subjects with meaningful information regarding the underlying logic of the decision engine. Explainable AI frameworks must translate complex mathematical weights into plain-language explanations. Individuals must also be granted simple mechanisms to contest automated decisions and request human intervention.
Data Subject Rights in Generative AI Models
Generative models present unprecedented structural conflicts with established data subject entitlements. Rights such as data erasure, rectification, and access were conceived for traditional databases, not deep neural networks. When a Large Language Model memorizes personal details, removing that specific information without retraining the whole model is technically challenging. Organizations deploying generative systems must solve these operational challenges to maintain legal compliance.
Data subjects retain the right to correct inaccurate facts generated about them by artificial intelligence tools. Implementing strict prompt filtering, retrieval-augmented generation (RAG) constraints, and output guardrails helps prevent factual hallucinations. If an individual requests complete erasure, companies must demonstrate effective unlearning techniques or execute targeted data deletion. Transparency portals must allow users to query what personal data was ingested during training. Fulfilling these individual rights requires continuous collaboration between privacy officers and software architects.
Technical Governance, Anonymization, and Cyber Security Safeguards
Protecting machine learning pipelines requires multi-layered cyber security architectures and strict data governance. Anonymization remains the ultimate safeguard, as truly anonymized data falls outside data protection scope. However, European regulatory authorities maintain extremely high standards for what constitutes true anonymization. Re-identification risks must be mathematically impossible, accounting for all reasonable external data sources.
Pseudonymized datasets still fall under data protection mandates and require full regulatory safeguards. Technical teams must enforce rigorous encryption standards across training data at rest and in transit. Role-based access controls must restrict internal developer access to sensitive training buckets. Regular vulnerability scanning and adversarial testing are vital to protect models against prompt injection, model inversion, and data poisoning attacks. Establishing precise data retention schedules ensures outdated training sets are purged automatically.

Harmonizing the EU AI Act with Existing GDPR Frameworks
Navigating modern European compliance requires managing two overlapping legal pillars. The EU AI Act operates as a product safety framework, while data protection law governs the underlying personal information. High-risk artificial intelligence applications must comply simultaneously with both legal structures. The AI Act introduces strict requirements for data quality, technical documentation, transparency, and post-market monitoring.
Organizations cannot use compliance with one regulation to excuse violations of the other. Data governance protocols required under Article 10 of the AI Act directly support data accuracy and minimization mandates. Combining your compliance audits into a single unified risk governance framework reduces administrative overhead. Regulatory authorities across Europe are coordinating enforcement actions, creating severe exposure for non-compliant enterprises. Integrated compliance strategies ensure long-term regulatory resilience across global markets.
Actionable Operational Blueprint for Enterprise AI Compliance
Transforming legal mandates into concrete software development practices requires structured organizational governance. First, establish a cross-functional AI Governance Board combining legal experts, cybersecurity specialists, and data engineers. Second, map all data flows feeding into internal and vendor-provided artificial intelligence models. Third, mandate pre-deployment risk evaluations for every prospective machine learning use case.
Fourth, deploy continuous monitoring tools to detect model drift, algorithmic bias, and security anomalies in real time. Fifth, train development teams on privacy-preserving coding practices and data hygiene. Sixth, maintain detailed processing records to satisfy statutory accountability mandates at a moment’s notice. Proactive operationalization turns regulatory friction into operational excellence, protecting both corporate reputation and customer trust.
The Ethics of Artificial Intelligence in Business: Where Are the Limits?
Low-Budget AI: Secret Ways to Cheaply Test AI Solutions Without a Big Budget
How to Get Started with AI in Your Small Business (Fast, Simple, Proven Blueprint)
Summary
Navigating compliance when working with artificial intelligence requires balancing technical innovation with strict data governance. Organizations must secure lawful processing grounds, implement privacy by design, conduct thorough risk assessments, and protect individual data rights. By aligning development workflows with data protection principles and the EU AI Act, enterprises build resilient, trustworthy software products.
Frequently Asked Questions (FAQ)
1. Can personal data be used for AI training without explicit user consent?
Yes, under specific conditions. Organizations can rely on legitimate interest if they conduct a formal assessment proving their interests outweigh individual privacy rights, implement strong technical safeguards, and offer an opt-out mechanism.
2. How does the “Right to be Forgotten” apply to trained AI models?
If personal data was processed unlawfully or consent is withdrawn, individuals can request data erasure. Organizations must remove the individual’s records from training datasets and either execute machine unlearning techniques, apply filtering, or retrain the model if data remains memorized.
3. Are synthetic datasets completely exempt from GDPR rules?
Synthetic data is exempt only if generated in a way that prevents any possible re-identification of real individuals. If synthetic data can be reverse-engineered to reveal underlying personal details, data protection mandates still apply.
4. What is the difference between GDPR and the EU AI Act?
GDPR regulates the protection and lawful processing of personal data. The EU AI Act is a risk-based product safety regulation focused on the development, deployment, and security of artificial intelligence systems. Both apply simultaneously.
5. What are the penalties for non-compliance in AI data processing?
Violations can result in fines up to €20 million or 4% of total worldwide annual turnover under GDPR. Furthermore, regulators can issue binding orders forcing the complete deletion of non-compliant datasets and trained models.
Call to Action (CTA)
Protect your organization from regulatory penalties and build trustworthy AI systems today! Download our comprehensive enterprise AI Compliance Checklist and schedule a technical consultation with our privacy engineering specialists to audit your training pipelines before your next deployment.